Agents · Product
Oct 2026Ran ~2,000 AI agents for 3 weeks: what it taught me about applied AI in product management
Two lead agents handed work to their helpers almost around the clock. The limit wasn’t compute or ideas. It was subscription quota.
Applied AI · Evals · Agents · Simulation
Applied AI product leader, currently on NVIDIA’s GenAI platform. Outside work I benchmark clinical scribes and coding agents, look inside language models, and simulate physics at 100 million particles.
I do it with a team of AI agents: two leads and their helpers, working almost around the clock. What it taught me about applied AI in product management
Agents · Product
Oct 2026Two lead agents handed work to their helpers almost around the clock. The limit wasn’t compute or ideas. It was subscription quota.
Interactive paper
Oct 2026Real numbers from Qwen models, turned into 3-D films and figures you can poke. Some pictures showed real mechanisms. Some were artefacts of the drawing.
Evals · VR
Oct 2026The bots knew the answer and followed a scripted path. A person in a headset didn’t. Each problem became a new test the same day.
Flagship · Evals
Sep 2026An open benchmark for ambient clinical documentation: seven speech recognizers, note generation, a LoRA fine-tune and a claim-level verifier. Then the same pipeline, live: a visit copilot that suggests the next question and drafts a cited note for review, on synthetic visits only.
Flagship · Interactive paper
Oct 2026Real activations, attention weights and replies from Qwen models, turned into 3-D films, walk-in VR scenes and seven live figures you can poke, including a map of the model’s vocabulary you can fly through. Each picture was checked against a measurement.
Evals · Agents
Apr–Oct 2026Eight loops that generate candidates, score them on local GPUs and keep the winners, from video and games to strange attractors and artificial life. The search was the easy part. The scorer needed the rigor.
Evals · Agents
Sep 202682 scored runs of local models and agent harnesses, and the grading bugs that had to be fixed first, including one that scored an answer 17/100 until a fixed extractor gave the same answer 97/100.
Evals · Video
Aug 2026Best-of-N on SyncNet chose lip-smacking takes, because SyncNet can’t hear mouth noise. Which faces can talk, and the tiered suite that now checks every render.
I lead a fleet of AI coding agents the way I’d lead a product team: clear specs, measured gates, and nothing ships on vibes.
Every handoff is written down, every job has one owner, and automatic gates catch regressions. That leaves me the parts agents can’t own: taste, priorities and anything public. Six stories from three weeks of it
App Store release pending
A physics-driven music visualizer and playground for Vision Pro, iPhone and Mac.
20/20 playable in our eval
Describe a world, get a playable simulation, for about $0.29 a game.
Live, with paying customers
An SEO service built for AI search.
Live
Pick a goal and see which supplements have the strongest research, in plain words.
iOS app + open engine
A mixtape app, and an open engine that finds where songs start in DJ mixes.
The Lab
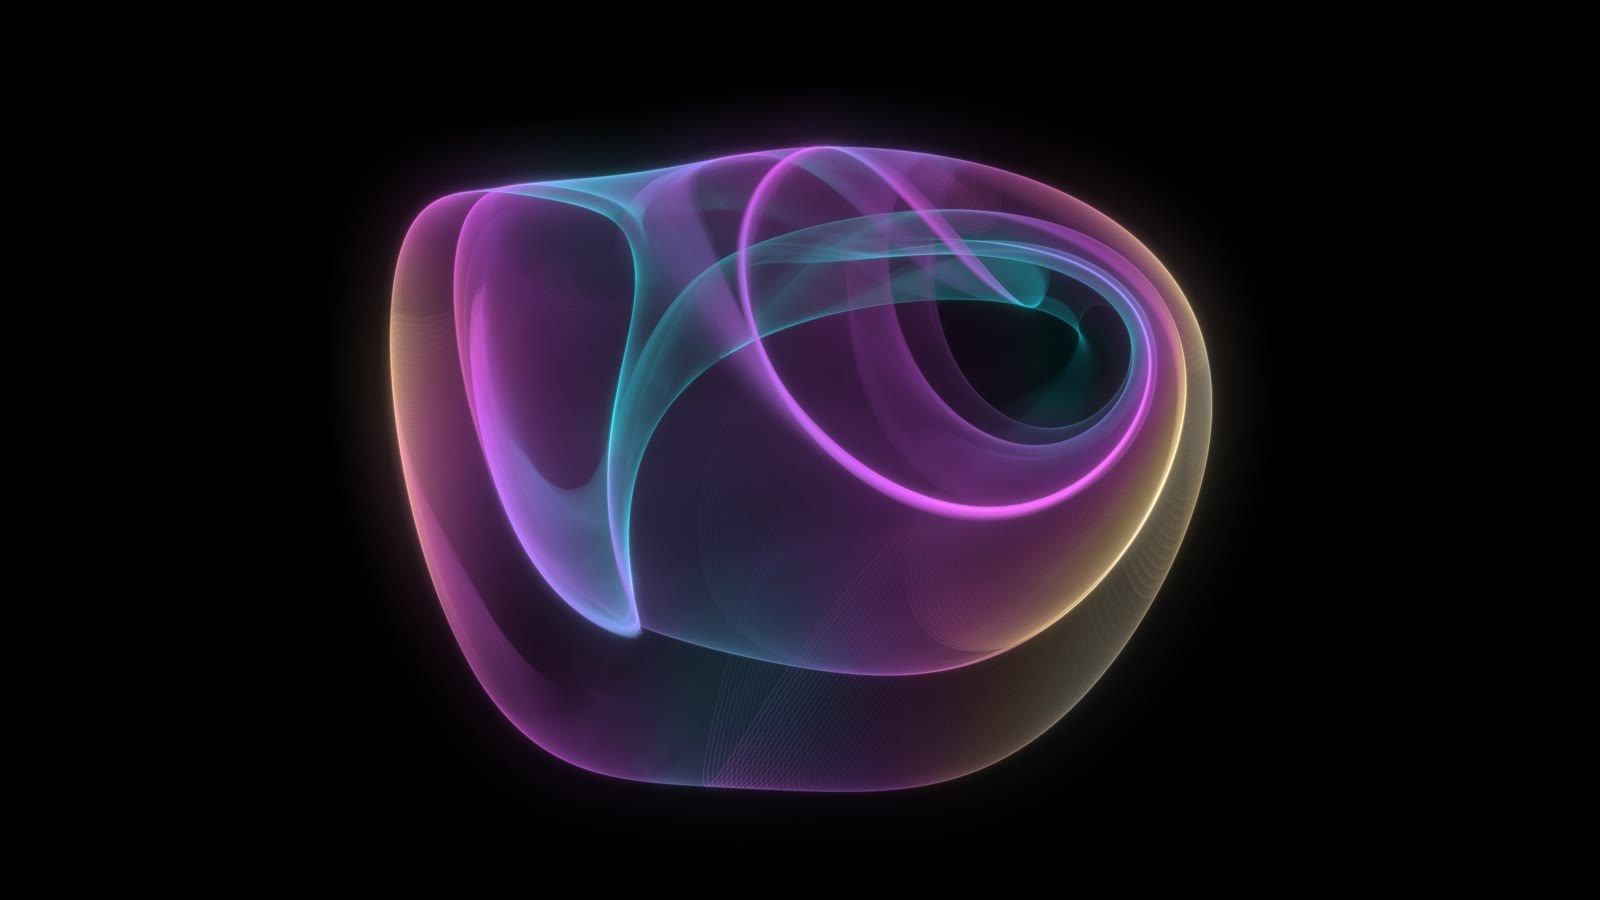
Discoveries II Strange attractors, searched 8 found in 2.5 billion random flows
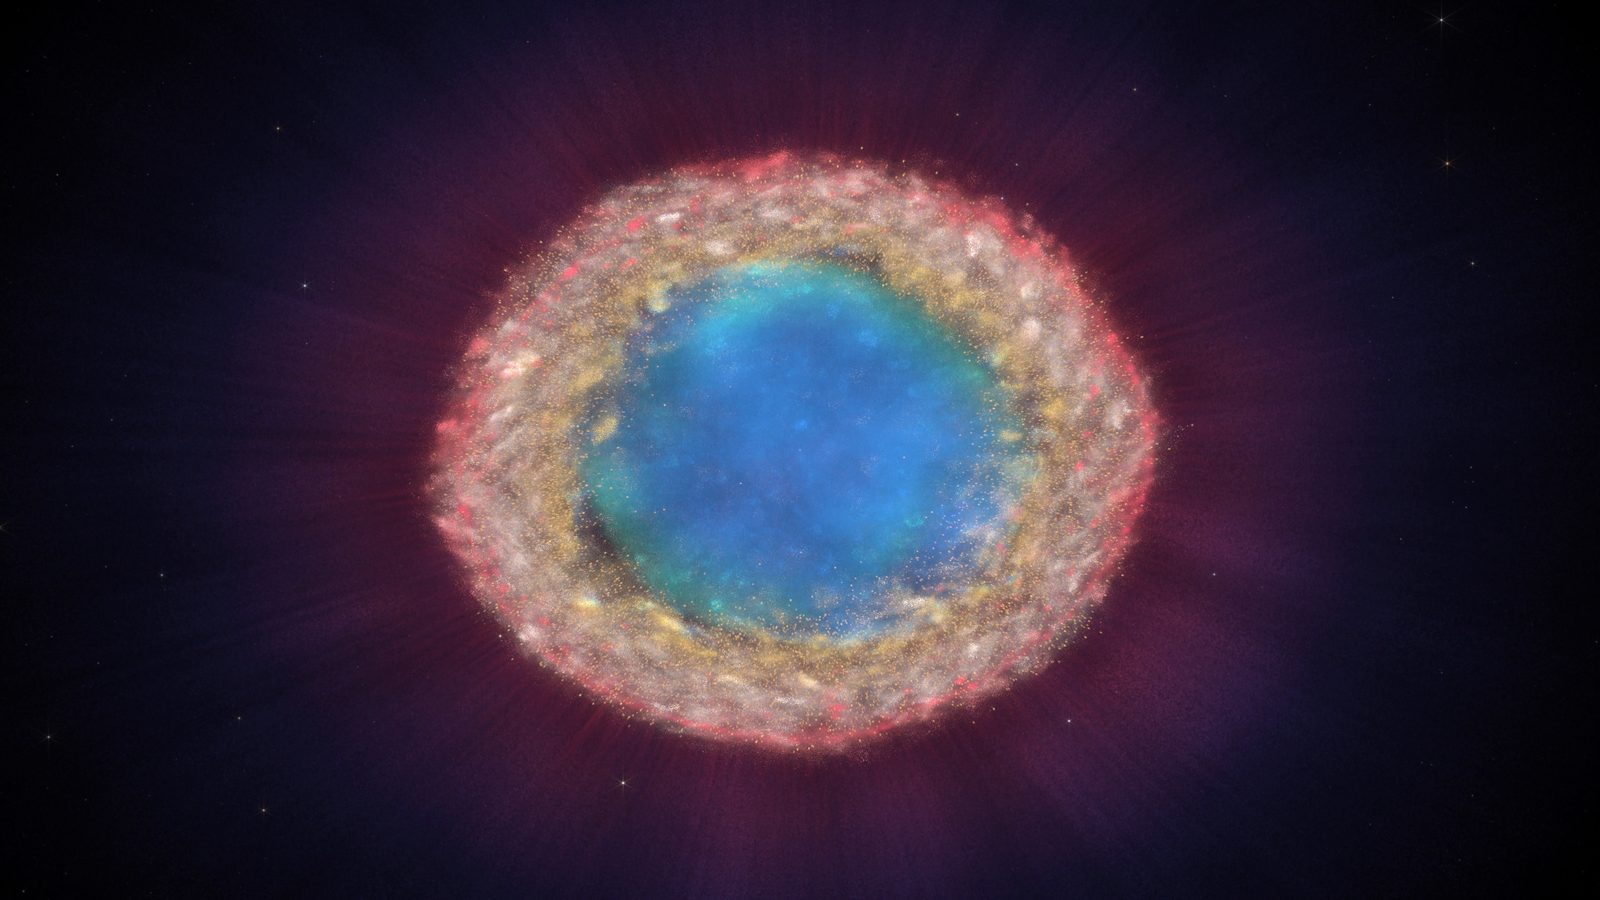
Ring Nebula Simulated nebula 250M particles, built from stellar-wind physics, not a photo
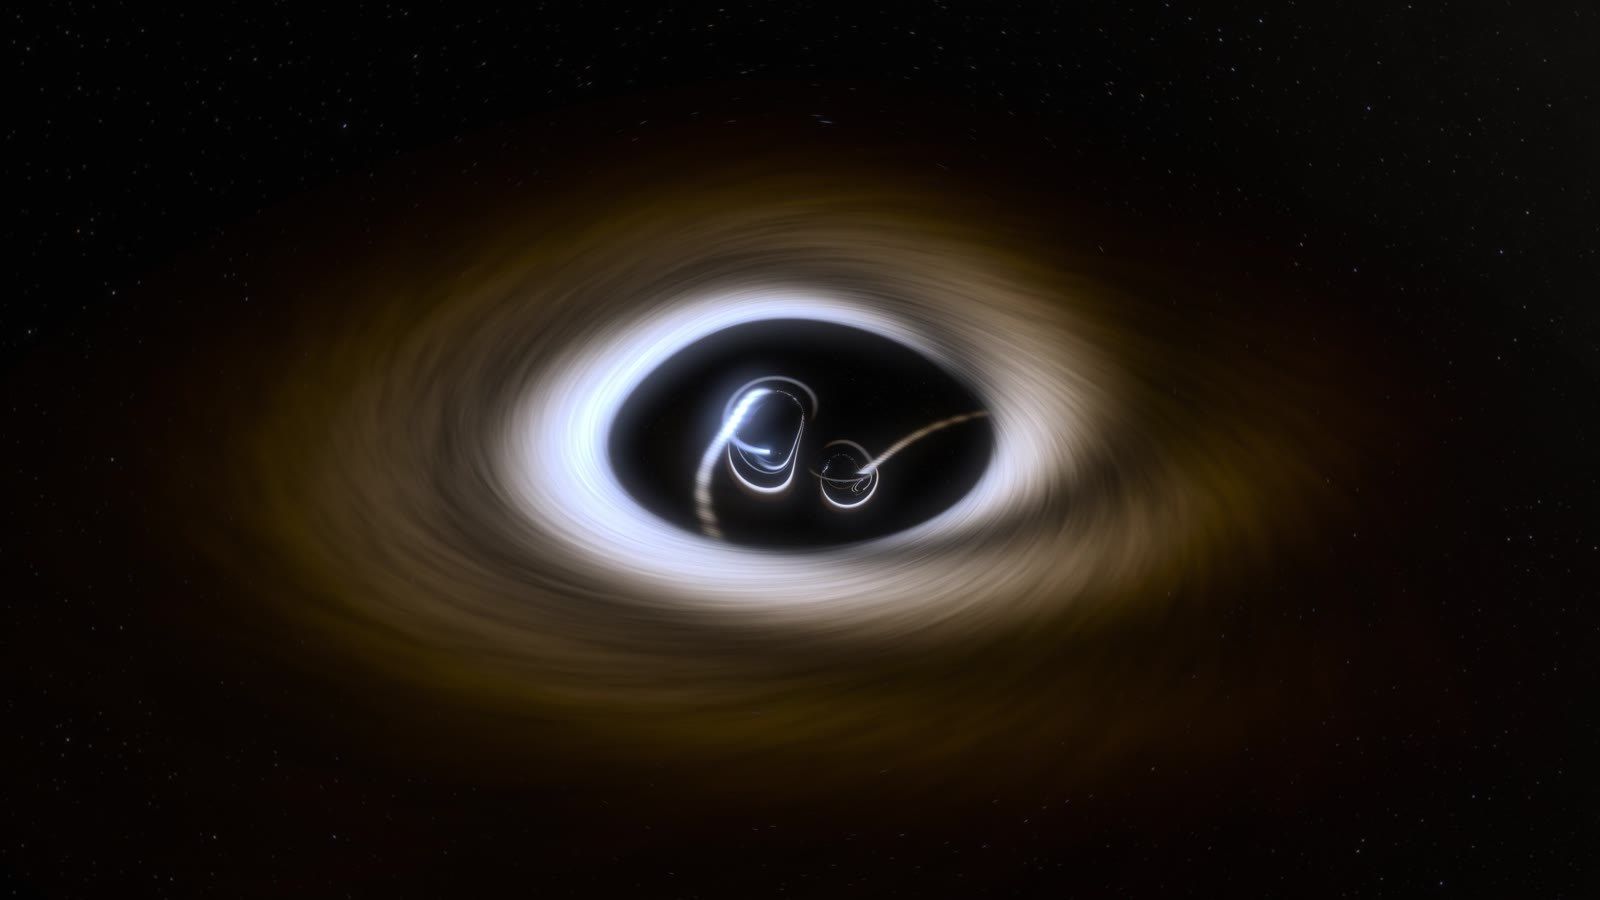
Binary Black Hole Merger GR ray tracer two black holes feed, spiral in, merge and ring down
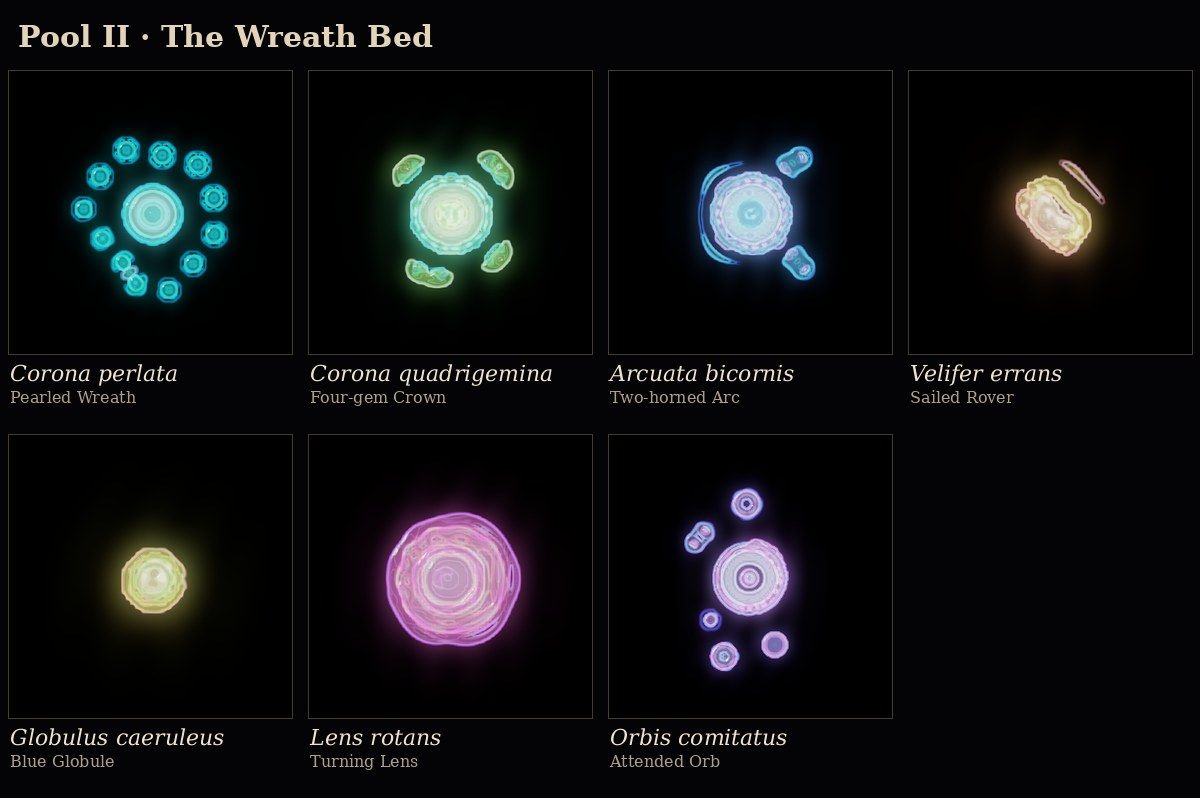
Bestiary Lifeforms found by search 24 species, one predator
Space and maths pieces run in your browser or in Vision Pro. Most of the Lab lives in Everdust, a physics-driven music visualizer for Vision Pro and iPhone. everdust.ai (opens in a new tab)
Half a million bot episodes a night proved the game worked, not that a person could play it.
A 3-D map of a model’s vocabulary kept fewer than half of each word’s true neighbours, and raw attention pointed at the wrong word.
One usage limit stopped 18 agents at once. The lesson: make every task resumable, and write every handoff down.
Two small models searching together marked 40 of 40 maths answers verified. 16 of them were wrong.
Before and alongside this: product at NVIDIA (GenAI platform), Lyft, Intuit, Meta and Visa.
Full résumé